Satsuma

The mapping language humans can read, machines can parse, and AIs can reason about.

Replace spreadsheets and wikis with a single source of truth for source-to-target data mappings. Clear enough for product owners to review, and precise enough for tools and AI assistants to build from.

customer_migration.stm
// Legacy Customer Migration

schema legacy_customers {
  CUST_ID     INT           (pk)
  CUST_TYPE   CHAR(1)       (enum {R, B, G})
  EMAIL_ADDR  VARCHAR(255)  (pii)       //! not validated
  PHONE_NBR   VARCHAR(50)                  //! mixed formats
  COUNTRY_CD  CHAR(2)
}

schema customers {
  customer_id  UUID          (pk, required)
  display_name VARCHAR(200)  (required)
  email        VARCHAR(255)  (format email, pii)
  phone        VARCHAR(20)   (format E.164)
}

mapping `customer migration` {
  source { `legacy_customers` }
  target { `customers` }

  CUST_ID    -> customer_id { uuid_v5("6ba7b...", CUST_ID) }
  EMAIL_ADDR -> email       { trim | lowercase | validate_email }

  -> display_name {
    "If @CUST_TYPE is R or null, concat @FIRST_NM + @LAST_NM.
     Otherwise use @COMPANY_NM. Trim and title-case."
  }

  PHONE_NBR -> phone {
    "Extract digits. If 10 digits assume US +1.
     For other patterns, determine country from @COUNTRY_CD."
    | warn_if_invalid
  }
}
See it in action

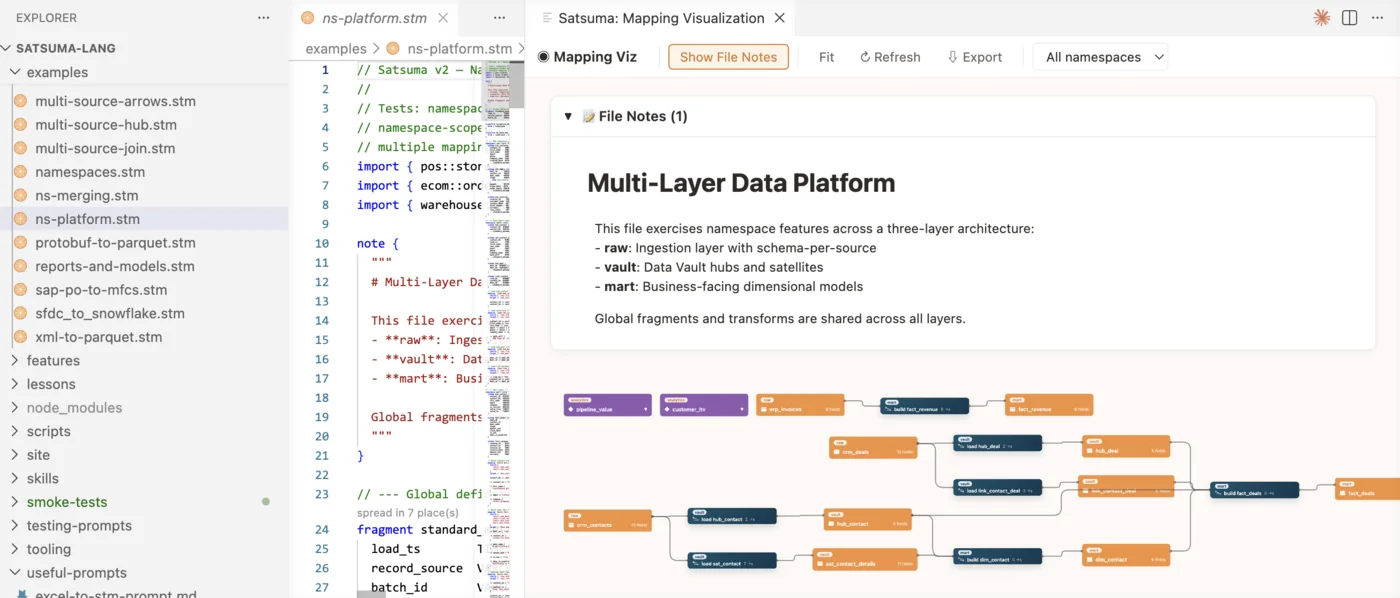
The VS Code extension gives you a live, interactive overview of your entire mapping workspace — schemas, mappings, and data flow — right alongside your code.

Satsuma VS Code extension showing the workspace overview with schema nodes, mapping blocks, and directional arrows
The Problem

Data mappings are scattered everywhere

In most enterprises, source-to-target mapping logic lives in spreadsheets, wiki pages, Confluence docs, YAML files, and tribal knowledge. Nobody trusts the docs and nobody can trace lineage.

Excel specs that are outdated by the time they're reviewed
No way to diff, lint, or validate mapping changes
Business rules hidden in cell comments, colour coding and a notes tab
The Solution

One language for all your mappings

Satsuma is a concise, beautiful, parseable format that becomes the single source of truth. Like DBML for database schemas, but for data mappings. Keep it in Git, check it with the parser, and write it by hand or with an AI assistant.

Text-based, diffable, version-controlled
Parser-backed tooling: lint, validate, lineage, graph
Exact arrows for the mechanical parts, plain English for the rules that need judgement
Extensible metadata

Your conventions. Your vocabulary.
No language changes.

Satsuma's ( ) metadata accepts any tag you invent, so you can describe what your organisation needs without waiting for a new version of the language:

  • ● Exotic file formats — COBOL copybooks, EDI qualifiers, HL7 segments, ISO 8583 bitmaps
  • ● Governance metadata — PII flags, classification, retention, masking, compliance frameworks
  • ● Pipeline construction — merge strategies, SCD types, match keys, refresh schedules
  • ● Analytics modelling — Kimball dimensions, Data Vault hubs, grain declarations, conformed keys
  • ● Your org’s standards — cost centres, data domains, audit levels, SLA tiers

Write down once what your tags mean. Everyone who reads the spec — analysts, engineers, and the tools and AI assistants they use — then works from the same definitions.

your_conventions.stm
schema payments (
  owner "payments-team",
  data_domain "finance",
  cost_center "CC-4200",
  audit_level high,
  compliance {PCI-DSS, SOX}
) {
  card_number  STRING   (pii, encrypt AES-256,
    mask last_four)
  amount       DECIMAL  (required)
}

Why teams choose Satsuma

Designed for real enterprise data mapping: legacy databases, EDI, COBOL and nested APIs.

Human-Readable

Product owners, analysts, and non-technical stakeholders can read and review mappings without learning a programming language. Natural language is first-class.

Machine-Parseable

Tree-sitter grammar with 330 corpus tests. The CLI, the editor and the visualisations all work from the same parse tree.

Version-Controlled

Plain text that diffs, merges and goes through pull-request review like any other code. Every change to a mapping has an author and a reason.

Works with AI Tools

The structure is regular, so AI assistants can read and write it too. satsuma validate checks what they produce.

23
CLI Commands
330
Parser Tests
1203
CLI Tests
378
LSP Tests

Real-world mappings, beautifully expressed

From legacy database migrations to enterprise platform modelling. Every construct serves a purpose.

db-to-db/pipeline.stm
// Legacy Customer Migration
import { `address fields` } from "../lib/common.stm"

note {
  """
  # Legacy Customer Migration

  Part of **Project Phoenix** — decommissioning the legacy SQL Server
  2008 instance by Q2 2026.

  ## Constraints
  - Runs in **batches of 10,000** to prevent memory issues
  - Target enforces referential integrity — addresses before customers
  - Estimated total: **2.4M records**, ~180 batches
  """
}

schema legacy_sqlserver (note "CUSTOMER table — SQL Server 2008") {
  CUST_ID       INT           (pk)
  CUST_TYPE     CHAR(1)       (enum {R, B, G})    //! some records have NULL
  EMAIL_ADDR    VARCHAR(255)  (pii)               //! not validated
  PHONE_NBR     VARCHAR(50)                         //! mixed formats
  COUNTRY_CD    CHAR(2)       (default US)
  CREDIT_LIMIT  DECIMAL(12,2)
  TAX_ID        VARCHAR(20)   (pii, encrypt)      //! plaintext in legacy
}

schema postgres_db (note "Normalized — PostgreSQL 16") {
  customer_id       UUID          (pk, required)
  customer_type     VARCHAR(20)   (enum {retail, business, government})
  display_name      VARCHAR(200)  (required)
  email             VARCHAR(255)  (format email, pii)
  phone             VARCHAR(20)   (format E.164)
  address_id        UUID          (ref @addresses.id)
  credit_limit_cents BIGINT       (default 0)
  tax_encrypted     TEXT          (pii, encrypt AES-256-GCM)
  ...`address fields`
}

mapping `customer migration` {
  source { `legacy_sqlserver` }
  target { `postgres_db` }

  CUST_ID -> customer_id { uuid_v5("6ba7b...", CUST_ID) }

  CUST_TYPE -> customer_type {
    map { R: "retail", B: "business", G: "government", null: "retail" }
  }

  -> display_name {
    "If @CUST_TYPE is R or null, concat @FIRST_NM + ' ' + @LAST_NM.
     Otherwise use @COMPANY_NM. Trim and title-case."
  }

  EMAIL_ADDR -> email { trim | lowercase | validate_email | null_if_invalid }

  PHONE_NBR -> phone {
    "Extract all digits. If 10 digits, assume US country code +1.
     Format as E.164. For other patterns, determine country from @COUNTRY_CD."
    | warn_if_invalid
  }

  -> address_id {
    "Create record in @addresses from @ADDR_LINE_1, @CITY, @STATE_PROV,
     @ZIP_POSTAL, @COUNTRY_CD. Normalize state to 2-char code.
     Deduplicate by normalized street + zip. Return UUID."
  }

  CREDIT_LIMIT -> credit_limit_cents { coalesce(0) | * 100 | round }

  TAX_ID -> tax_encrypted {
    error_if_null | encrypt(AES-256-GCM, secrets.tax_encryption_key)
  }
}

Built for your role

Satsuma serves the entire data team, from architects to product owners.

Professional tooling, built-in

Every tool works from the real parse tree, so results are exact and repeatable.

No installation required

Works without the CLI or VS Code extension

The tools help, but a .stm file is useful on its own. Locked-down laptop? Working through a web chat assistant? You still get the core benefits.

Readable on its own — a .stm file makes sense in any text editor or on GitHub, with nothing installed.
Plain text, version-controlled — .stm files diff cleanly and merge naturally in any Git workflow.
Works with any LLM — paste the compact grammar reference into ChatGPT, Gemini, or Claude.ai and start writing specs.
Graduate when ready — when your environment allows installation, the CLI and extension slot in without changing your files.
Read the full guide →

Example workflows without tooling

1

Draft specs from requirements

Upload a spreadsheet or requirements doc to any LLM and ask it to produce a .stm file.

2

Review and explain specs

Paste a .stm file and ask for a walkthrough, risk assessment, or onboarding summary.

3

Generate implementation scaffolds

Ask the LLM to produce dbt, PySpark, SQL, or pandas code from your mapping spec.

4

Use Agent Skills

Drop-in Agent Skills for Excel ↔ Satsuma, dbt ↔ Satsuma, OpenLineage export, synthetic test data, and plain-English spec explainers.

Frequently asked questions

Everything you need to know about adopting Satsuma.

Can non-technical people read Satsuma?

That's the primary design goal. The syntax reads like a structured document, not a programming language. Product owners, business analysts, and other non-technical stakeholders can follow the arrows (source_field -> target_field), understand metadata like (pii, required), and read natural-language transform descriptions directly. No programming experience required — there's a dedicated tutorial for non-technical readers to get started in minutes.

Does Satsuma replace dbt, DBML, PySpark, or my existing data tools?

No. Satsuma is not a pipeline engine or a schema modelling tool. It is a specification language that sits upstream of your implementation stack. You write your mapping intent in Satsuma, then use that spec to generate or validate implementations in dbt, PySpark, pandas, SQL, DuckDB, or whatever your team runs. Think of it as the blueprint, not the building.

Why not just use YAML, JSON, or a spreadsheet?

Spreadsheets are easy to start and hard to keep right: layouts differ from team to team, changes don't diff cleanly, and meaning hides in cell colour and comments. YAML and JSON fix the diffs, but they are hard to read at a glance and every team invents its own shape.

Satsuma has one shape, fixed by a grammar, and it reads like a document. A mapping looks the same whoever wrote it, and satsuma validate and satsuma lint tell you whether a spec is structurally right.

How does Satsuma work with AI coding assistants?

AI coding assistants such as GitHub Copilot, Claude Code and Cursor can read and write .stm files, and can use them to draft implementations for dbt, Databricks, pandas, PySpark, DuckDB and similar stacks. Satsuma keeps exact field mappings, types and value maps apart from plain-English business rules, so it is clear which parts can be implemented directly and which need a person's judgement. Review what an assistant produces as you would any other code.

Satsuma also ships Agent Skills (following the agentskills.io standard) for Claude Code and Claude Desktop: convert Excel ↔ Satsuma, reverse-engineer specs from dbt, scaffold dbt projects, generate synthetic test data, export OpenLineage events, and produce plain-English spec explanations for stakeholders.

What if I'm not allowed to install the CLI or don't have any agentic coding tools?

You can still get real value. Satsuma files are plain text — write them in any editor and version them in Git. For AI assistance, paste the compact grammar reference into any web LLM like ChatGPT, Gemini, or Claude.ai. That's enough for the model to generate, review, and explain Satsuma specs. No CLI, no VS Code, no agent required. Read the full guide for workflows and tips.

What tech stacks can I target from a Satsuma spec?

Satsuma does not depend on any stack. The same .stm file can guide implementations in dbt (Snowflake, BigQuery, Redshift), Databricks Lakehouse Declarative Pipelines, PySpark, pandas, DuckDB, dltHub, SQL stored procedures, Apache Beam and more. Integration teams use the same specs for flows in webMethods, MuleSoft, Azure Logic Apps, cloud microservices and other middleware. The mapping spec is the contract; the implementation target is your choice.

How mature is Satsuma? Is it production-ready?

Satsuma is in an early experimental stage. The language spec, parser, CLI, and VS Code extension are functional and well-tested, but the project is young and evolving. We're actively looking for feedback from data engineers, integration teams, and anyone who works with mapping specs. If you try it, we'd love to hear what works and what doesn't — open an issue or start a discussion on GitHub.

Satsuma

Ready to simplify your data mappings?

Satsuma is open source and free. Start mapping in minutes.